An MVP proves that someone wants the thing. Scaling it is a different job, with different failure modes, and most of them are not the ones the advice columns warn you about. The usual guide to "scaling your startup" is about hiring, fundraising and culture. This one is about the product and the codebase, because that is where we watch the transition go wrong.
We have built over a hundred products for clients and we run three of our own, including Denti360, a practice-management platform that real multi-branch dental clinics use every day. Running our own products is what changed our view of this. It is easy to hand over an MVP and call it done. It is much harder to be the people still operating it eighteen months later, and that experience is what the advice below is drawn from.
First, be honest about what your MVP is
Three very different things get called an MVP, and which one you have decides whether you scale it or replace it.
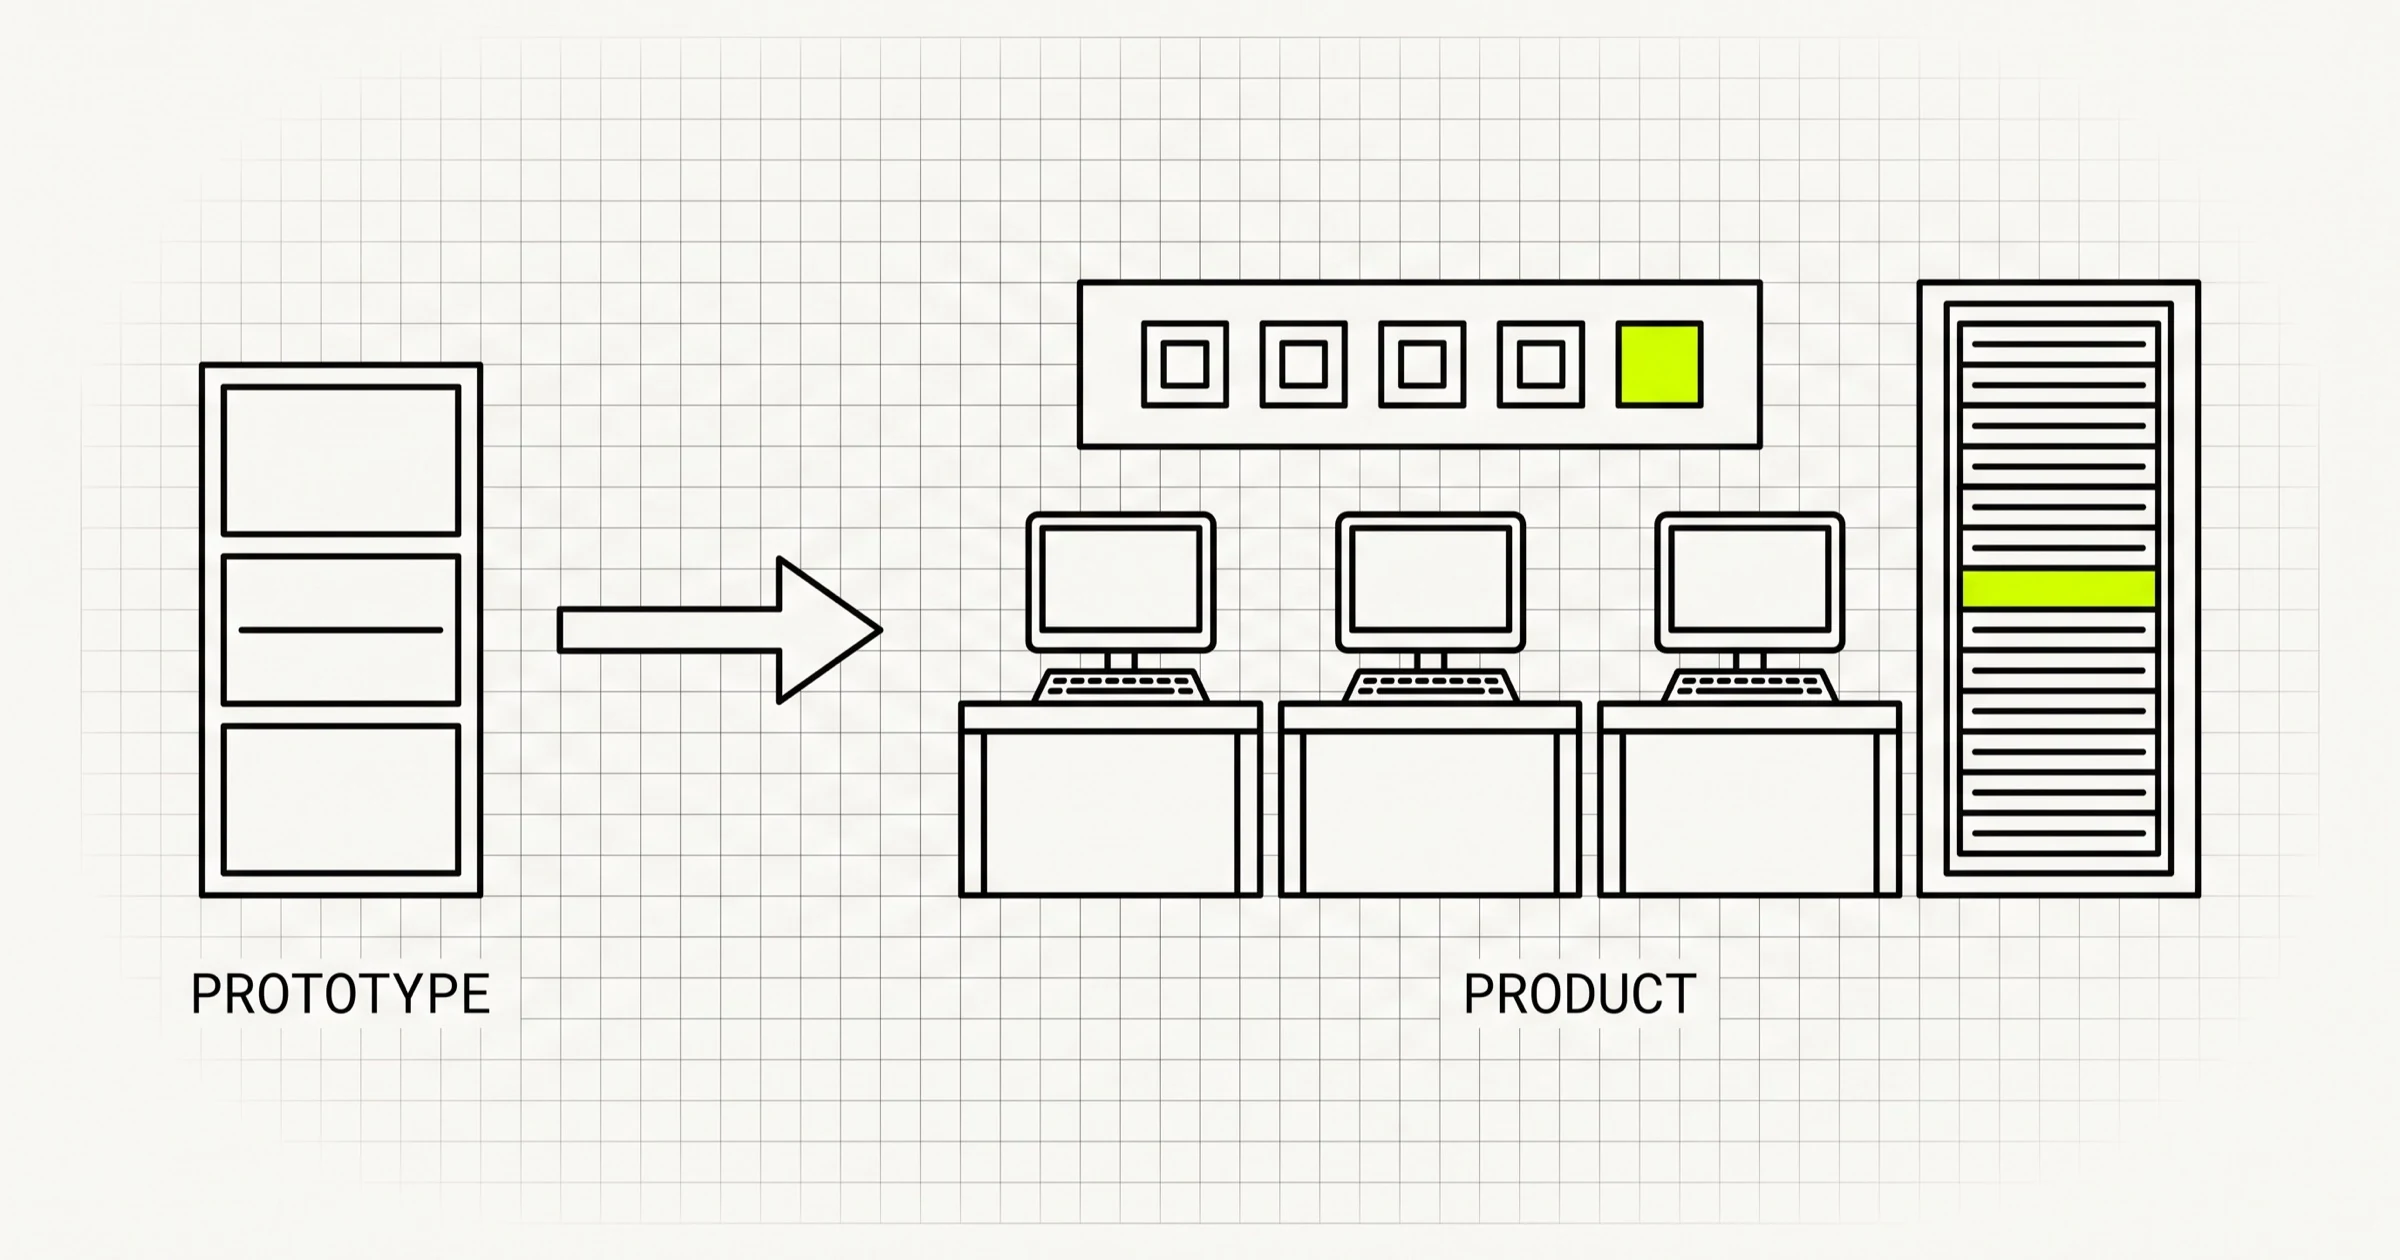
A prototype. Built in days or weeks to show an idea, usually on whatever was fastest. The data model was never designed, it accreted. If this is what you have, do not scale it. Keep it as the specification for the real build and start again. Every month spent extending a prototype is a month spent making the eventual rewrite more expensive.
A proof. One workflow, built properly, with real users on it. The scope is narrow but the foundations were laid with the next twelve months in mind. This is what our MVP development work aims to produce, and it is the version you can scale rather than replace.
An accidental platform. The MVP that quietly became the product, with customers, revenue, and two years of decisions nobody wrote down. Nobody plans this. Most successful startups end up here anyway.
The test that separates them is not code quality. Ugly code with the right data model can be scaled. Beautiful code with the wrong data model cannot. If the shape of your data has to change to support what comes next, you are looking at a rebuild whatever the linter says.
The five things that do not survive the prototype
These are the parts of an MVP that almost always have to be rebuilt, in roughly the order they start hurting.
1. The data model, and especially tenancy
The single most expensive sentence in any scaling plan is "we'll add multi-tenancy in phase two." Every table, every query, every permission check and every report has to know which customer, branch or workspace it belongs to. Designed in at the first migration, that costs a few thousand dollars once. Added later, it is not a feature, it is a rewrite of the application while paying customers are using it.
Denti360 was designed with branch scoping in the schema from the start, which is why a clinic opening a fourth location is a configuration change rather than a project. We did not do that because we were clever. We did it because tenancy is the one thing we are most confident is painful to retrofit, and we did not want to find out again on our own product.
2. Permissions
An MVP has an admin and a user. A product has an owner, a manager, a staff member, a read-only auditor and a support role that can see everything and change nothing. A permissions model is not a feature you finish. It is a tax applied to everything built afterwards: every new screen needs an answer, per role, about who can see it and who can change it, and a test for each. Our MVP cost guide puts it bluntly: a fourth user role always costs more than a third API. Budget for it as a percentage on every feature, not as a line item.
3. The manual steps hiding behind the product
Every MVP is held together by a founder doing things by hand: creating accounts, importing a customer's data, flipping a flag in the database, sending the onboarding email. At ten customers this is fine. At a hundred it is someone's whole job, and at a thousand it is the reason growth stalled. Internal tooling is easy to defer because no customer ever sees it, which is exactly why it gets deferred past the point where it hurts. Every manual step in onboarding is a tax on growth, paid in someone's afternoon, forever.
4. Billing that was "just Stripe Checkout"
The MVP took a card and that was that. The product needs plan changes mid-cycle, proration, part payments, refunds, discounts someone promised on a call, invoices that must be reprintable unchanged a year later, and tax that differs by where the customer sits. None of that is technically hard. All of it is detail, and billing is the one screen where a bug does not annoy the user, it embarrasses them in front of their own customer. On Denti360, billing took longer than any row in our feature table implied, and it is the area we would budget most generously if we started again.
5. What the words mean
This one is invisible until it is expensive. In an MVP, "active user", "completed order" or "finished treatment" mean whatever the one developer decided that afternoon. As the product grows, appointments, records and billing each decide independently what those words mean, and the first dashboard that tries to reconcile them exposes three different answers. Agree the handful of nouns the whole product reports on before you build the second feature. It is a one-day conversation that repays itself for the life of the product.
What "global" actually changes in the code
Founders hear "global" and think translation. Translation is the least of it. The things that actually change are these.
- Money. Currencies, rounding, tax rules, and which countries your payment provider can pay out to. That last one is a hard constraint on which markets you can serve, and it is worth checking before you promise a market you cannot pay. Our Stripe Connect guide goes into what that looks like for a marketplace.
- Time. Anything with a calendar, a deadline or a schedule now has a timezone problem. A booking system that stored local times without zones works perfectly until the first customer in a second country, and then it silently double-books.
- Regulation. Compliance scope is set by the market, not by the product. A version of Denti360 sold into the United States would carry HIPAA obligations, BAA-eligible infrastructure and audit logging as first-class requirements from day one. The same product elsewhere carries a different set. Do not copy a compliance budget from a product built for a different jurisdiction, and do not assume the one you have transfers.
- Data residency. Some customers, and some regulators, will require that their data stays in a region. If your architecture assumes one database in one place, that is a structural change rather than a setting.
- Language, last. Localisation matters, but it is the one item on this list that can be added late without touching the data model. Do the other four first.
The order we would do it in
Running our own products changed the order we recommend. Four things move earlier than instinct suggests, and one moves much later.
Settle the vocabulary first. See point five above. Dashboards are usually scheduled last, which is why they surface the problem last.
Make the product describable before you scale the team. The bottleneck in moving from two engineers to eight is rarely hiring, it is that nobody can explain the product precisely enough for a new person to build a consistent piece of it. On Nestlet, our lease marketplace currently in build, we wrote a full design guideline document before the first screen, so the build could be handed to developers, or to coding agents, and come back looking like one product. That document cost days. The inconsistency it prevented would have cost weeks.
Build the boring tooling early. Admin screens, onboarding automation, the ability to impersonate a customer to see what they see, a way to fix data without opening a database client. These convert directly into support hours saved, and support hours are the most expensive engineering hours there are.
Test the restore, not the backup. Every MVP has backups. Very few have ever restored one. The first time you find out the backup was incomplete should not be the day you need it.
Hold off on microservices. This is the one that moves later, and it is where we disagree with most scaling advice. A well-structured monolith with a proper CI pipeline, a queue for background work and one good database will carry a product far past the point where most startups run out of other problems. Splitting into services before you have a team per service trades a codebase problem for a distributed-systems problem, and the second is harder. Split when a specific part of the system has a different scaling profile or a different team, not because a diagram says you should.
The same goes for native mobile. Denti360 is a responsive web application because clinic staff work at a desk with a screen in front of them. Adding iOS and Android would have swung the project total by thirty to fifty percent and bought almost nothing. Add platforms when usage proves they are needed, not when a competitor's app store listing makes you nervous.
What it costs to keep it alive
Every build-cost article stops at launch. Launch is where the interesting part starts, and two costs are systematically underpriced.
Support tracks your growth rate, not your customer count. A customer in their first month asks questions constantly. The same customer in month six barely contacts you. So support load is driven by how many customers are new, which means the faster you grow, the worse it gets, which is exactly backwards from how most people budget it.
Maintenance is a fixed allocation, not an interruption. Dependencies age, browsers change, a payment provider deprecates an API version, and a quarterly report turns out to have been wrong since March. None of this is on a roadmap. Our planning number from running Denti360 is ongoing engineering of fifteen to twenty percent of the original build cost per year just to keep the product current, before any new features. That is roughly one experienced developer for a few days a month, which is what it actually takes.
The MVP cost guide covers the build side of this arithmetic, and our Denti360 cost breakdown shows it applied to one real product line by line.
When not to scale yet
Scaling a product that has not earned it is the most expensive mistake on this page, because everything above costs money and none of it creates demand. Three signals that the MVP is not ready:
- Retention is flat or falling. If the users you already have are not coming back, more users will not fix it. Scaling multiplies whatever you have, including the problem.
- Every customer needs something custom. If closing each deal requires a change to the product, you do not have a product yet. You have a services business with a demo.
- You cannot say what the product is in one sentence. If the team cannot, the codebase will not be able to either, and the new engineers you hire to scale it will each build a different product.
If those are in order, the job is sequencing, and that is something we can do with you. Our end-to-end product development work is built for exactly this stage: taking a proven MVP and turning it into a platform that survives its own growth, with the data model, permissions, tooling and billing done in the right order.
Sitting on an MVP that is starting to creak? A Scoping Sprint ($2,300, two weeks) ends with a technical plan that sequences exactly this, a prototype of what comes next, and a fixed quote. Or just start a conversation.