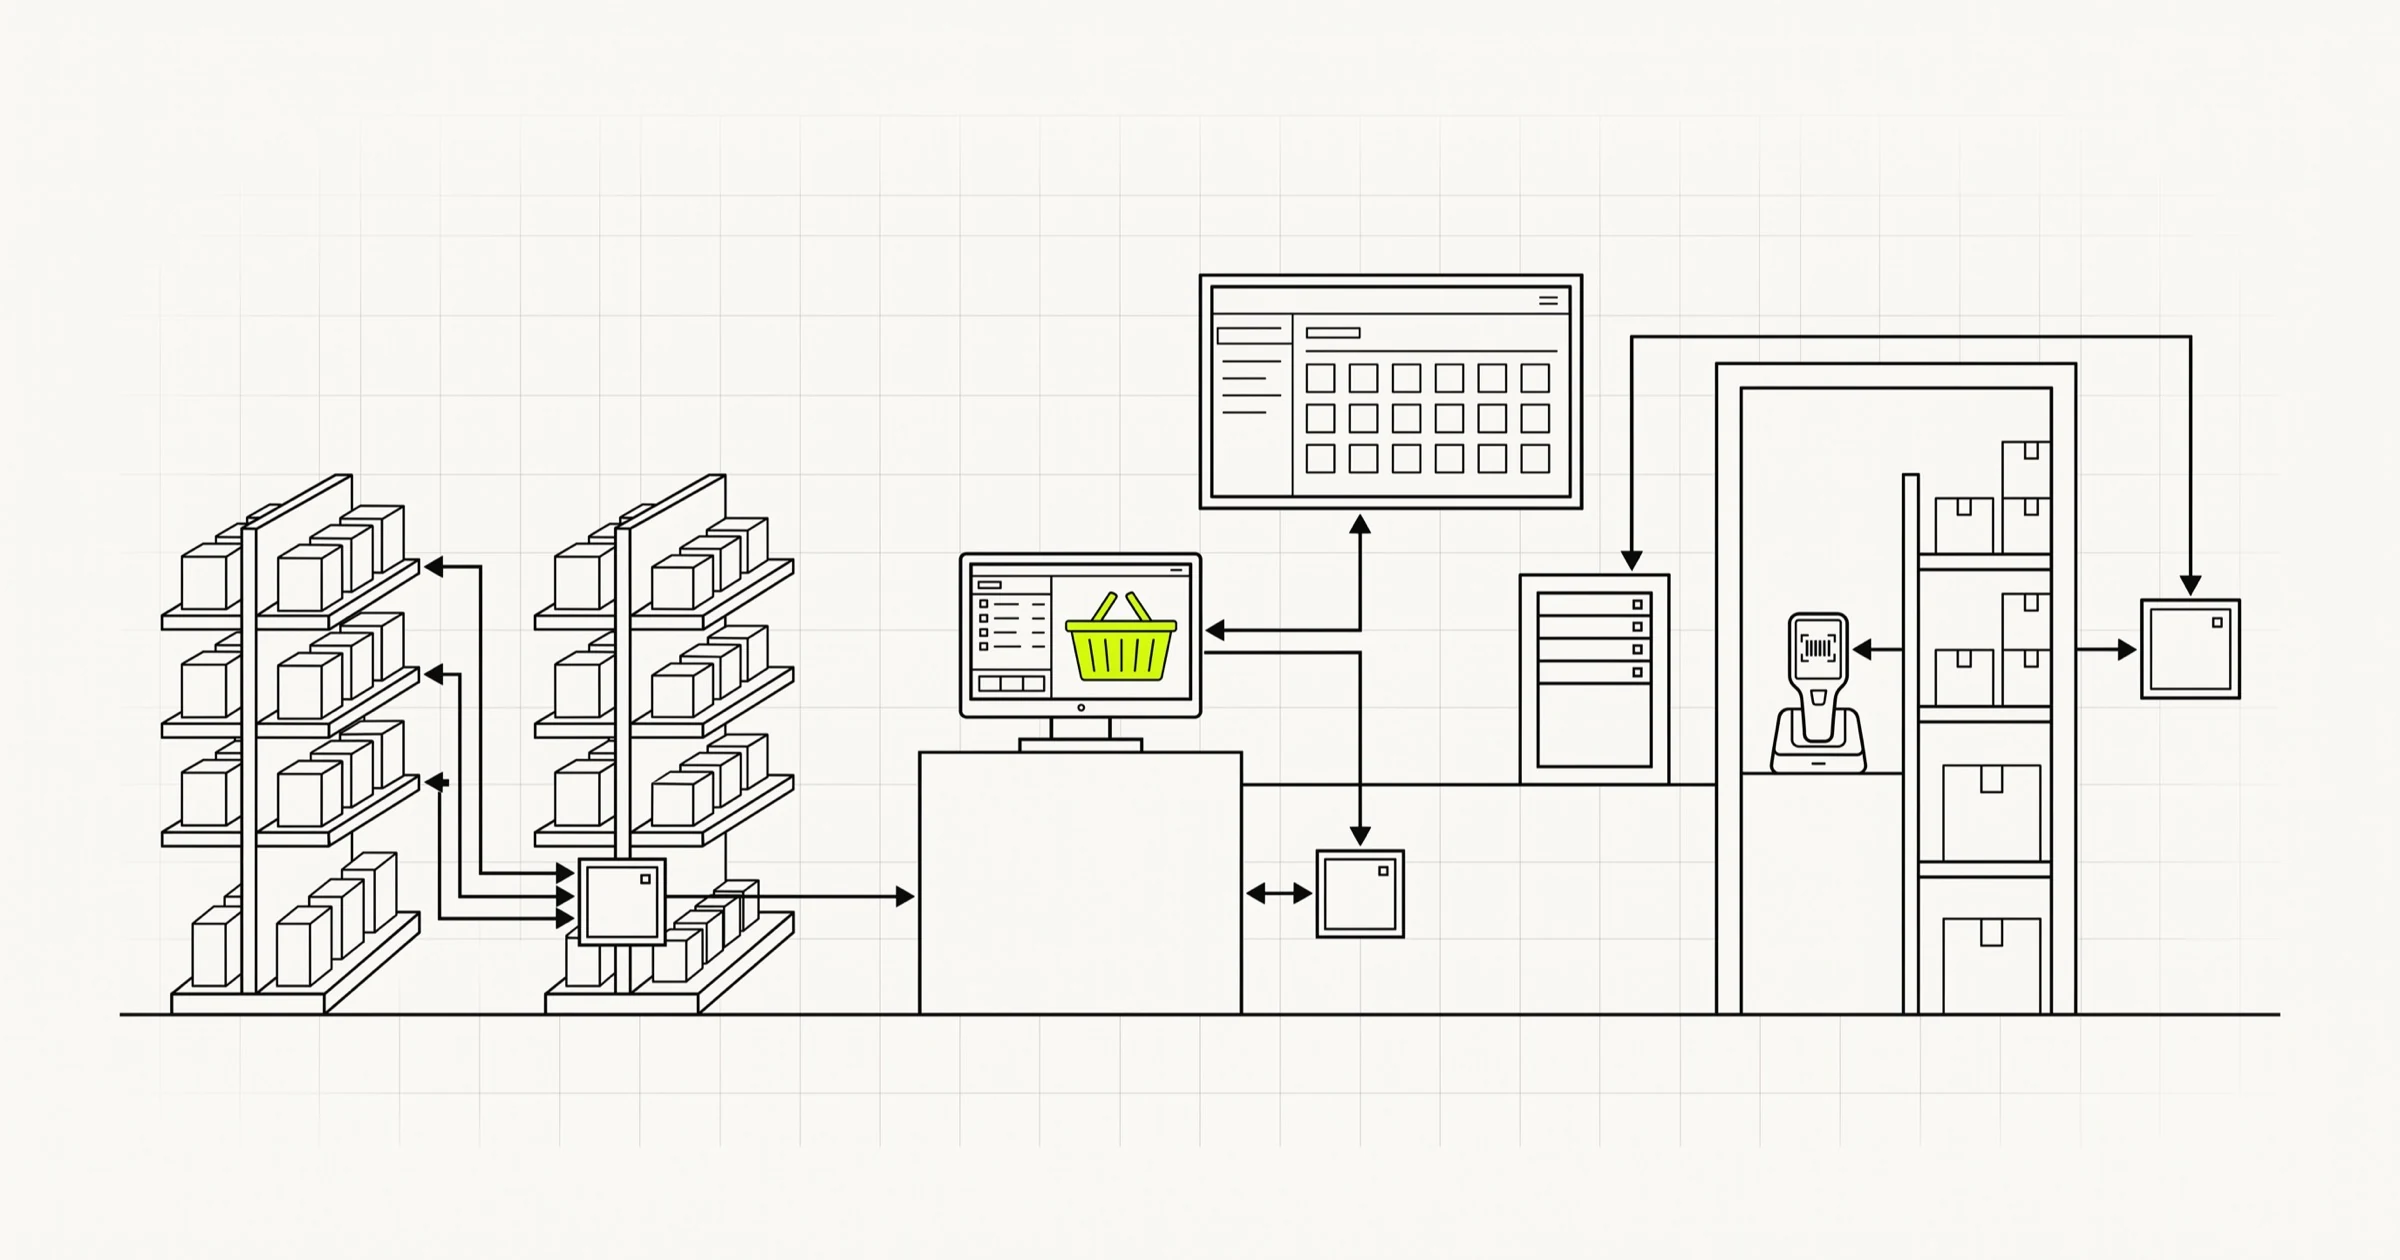
"Add AI personalization to our ads" is almost never a model problem. It is a data plumbing problem with a model bolted on at the end, and the plumbing is where the budget goes.
A product owner gets handed this ask in a fairly standard way. Marketing has seen what a large marketplace does with recommended products and retargeting, someone has read a vendor deck, and the request lands as a feature: personalise the ads. The engineering team then discovers that the interesting part, the ranking model, is maybe a fifth of the work, and that the other four fifths are things nobody scoped because they are not glamorous.
This is a walk through the actual parts: what each layer does, what it costs to run, which decisions are reversible, and where these projects tend to die. It also covers the case most write-ups skip, which is the situation where you should not build any of this because a rules engine and a merchandiser will beat a model for a fraction of the money.
What an ad personalization system is actually made of
Bottom to top, there are five layers. Every real system has all five, whether or not anyone named them.
1. Collection
Events from the web tag, the mobile SDK, and the server. Page views, product views, add to cart, search queries, purchases, ad impressions, ad clicks. The thing that separates a usable collection layer from a broken one is that consent state is attached to each event at the moment of capture, not looked up later.
2. Identity
Turning a device or a cookie into a stable subject you can accumulate history against, and knowing precisely when you cannot. Anonymous browsing, then login, then a second device, then a shared family tablet. This layer decides what "a user" means everywhere above it.
3. Storage and features
A raw event log you can replay, a derived profile per user, and the catalogue itself as structured data. The catalogue matters more than people expect: a ranker that cannot see attributes, price, stock and margin is ranking blind.
4. Candidate generation and ranking
Two distinct steps that get collapsed in conversation. Candidate generation cuts two hundred thousand items down to a few hundred, cheaply. Ranking orders those few hundred, expensively. Confusing them is how teams end up trying to score an entire catalogue inside a request.
5. Delivery and measurement
Serving inside a latency budget, logging what was shown and why, and holding out a slice of users so you can tell whether any of it worked.
The model is item four, and it is usually the cheapest piece to build. Libraries and managed services have made the algorithm the commodity part. Teams start there because it is the part that feels like the project.
The identity and event layer is where these projects die
If a personalization programme is going to fail, this is where. Not dramatically. It just never gets good, and after two quarters someone turns it off.
The failure mode is boring. Product IDs in the analytics stream do not match product IDs in the catalogue, because merchandising deletes and recreates SKUs when a variant changes, so the recommender confidently returns items the storefront cannot render. Or the mobile SDK fires an add_to_cart event with a different payload shape than the web tag, and half of a user's history is invisible to the feature job. Or ad blockers eat a large slice of client-side events in a pattern that correlates with exactly the audience you wanted.
One concrete test is worth applying before any model work begins. For a randomly chosen user, can you produce every event you hold about them, in order, with the consent state that applied at the time of each one, in a few seconds? If that means joining three systems by hand, the model layer is premature. The same query is what a deletion request needs, so you have to build it regardless.
Some decisions here are effectively permanent:
- Event schema. One versioned contract shared by web, mobile and server. Adding a field later is easy. Changing what an existing field means is not, because your history now means two things.
- Server-side versus client-side collection. Server-side is more reliable and harder to instrument. Most teams end up with both and need a rule for which wins on duplicates.
- Anonymous to known stitching. On login, do you backfill the anonymous session into account history? Yes gives better cold-start behaviour. Yes done carelessly merges two people who share a browser.
- Whether you keep raw events at all. Aggregating early is cheaper and permanently destroys your ability to build a feature you have not thought of yet.
Catalogue integrity, stock accuracy and identity are ordinary commerce plumbing problems long before they are AI problems, which is why this work belongs with the team that already owns retail and e-commerce engineering rather than with a separate data science effort.
Rules, collaborative filtering, and learned ranking are three different projects
These get discussed as points on a sophistication scale. They are better understood as different engineering commitments with different failure modes, and most retailers should be honest about which one their data actually supports.
| Approach | What it needs | What it costs to run | Where it breaks |
|---|---|---|---|
| Hand-written rules and segments | A clean catalogue, a handful of attributes, someone with merchandising judgement | Config plus periodic human attention. No training infrastructure, no serving model. | Rule count. Past roughly a few dozen interacting rules nobody can predict the output any more. |
| Content and attribute similarity | Good structured attributes or usable text and images per item | One batch job producing an item-to-item neighbour table. Cheap and very stable. | Recommends more of the same thing. Someone who bought a mattress gets shown mattresses. |
| Collaborative filtering | Enough interactions per item that co-occurrence is signal rather than noise | A recurring training job plus a key-value store of precomputed neighbours or vectors. | Cold start, popularity bias, and long-tail items that never accumulate enough interactions. |
| Learned ranking on logged interactions | Impression and click logs including what was shown and not clicked, plus a feature pipeline | Training pipeline, feature store, online serving, monitoring for training and serving skew. | Feedback loops. The model learns from traffic it caused, so it reinforces its own past choices. |
| Contextual bandit on top of any of the above | Reliable reward logging and the willingness to spend impressions on exploration | The above plus per-decision propensity logging and a real experimentation discipline. | Reward definition. Optimise clicks and you get clickbait, optimise revenue and you get expensive items. |
The jump that costs real money is from the third row to the fourth. Collaborative filtering can live as a nightly job and a lookup table, which a normal backend team can operate. Learned ranking introduces a training pipeline, a feature store, and an online service whose behaviour has to match its offline evaluation. That is a standing operational commitment, not a delivery.
One detail from that fourth row silently determines whether any of it is possible. Learned ranking needs negatives: items that were shown and not clicked. If you do not already log impressions with the item set and position, you have no training data and will not have any until you ship logging and wait. That wait is often a month or two, and it belongs in the plan.
Cold start is the hard problem, not the model
Every serious personalization system spends most of its engineering effort on the cases where it knows nothing. There are three separate cold starts and they need different answers.
New user. First session, no history, quite possibly no consent. On a retail site this is a large share of traffic and often the majority. Whatever you serve here is served constantly, so treat the no-history path as the main path, not the fallback.
New item. A product added this morning has no interactions, so any co-occurrence method will never surface it, so it never gets interactions. Content and attribute features break that loop by letting a new item inherit signal from what it resembles.
New market or locale. Launch in a new country and the model carries over preferences that do not hold. Season, climate, sizing conventions and price sensitivity all shift at once.
The tactics that work are unglamorous. Popularity priors segmented by entry context rather than global, since someone landing on a hiking boot page from a search ad is not an average visitor. Content features so new items are reachable on day one. A small fixed exploration budget, some low single-digit share of impressions deliberately spent on unproven items, treated as the cost of keeping the catalogue discoverable.
Above all, design the fallback chain before the model: personalised ranking, then segment-level, then contextual ranking from the current page, then curated defaults. Every step returns a full result set and the whole chain has a hard timeout. This chain runs far more often than the top of it does, and during a partial outage it is the only thing between you and empty ad slots.
Real-time scoring costs more than batch, and often buys less
The instinct is to score in the request. Sometimes that is right. Frequently it is an expensive way to buy a marginal improvement.
| Mode | How it works | What it costs | Use when |
|---|---|---|---|
| Batch | Precompute top N per user on a schedule, write to a key-value store, serve by lookup | One scheduled job and a cache. Latency is a key lookup. Operationally quiet. | Preferences move slowly. Email, retargeting audiences, homepage modules. |
| Hybrid | Batch candidates, re-ranked in the request using session context and current stock | Batch cost plus a small stateless service. Feature freshness limited to the session. | Most retail cases. This is the default worth arguing against, not for. |
| Real-time | Features computed and the model called inside the request | An online feature store, a p99 latency budget, autoscaling, and skew monitoring. | Intent changes within a session in ways that matter. Travel, tickets, volatile inventory. |
The real cost of the third row is not compute. It is that two code paths now compute the same features, one in training and one in serving, and they will drift. Training and serving skew is subtle, degrades quality slowly, and raises no alert. Catching it means logging the features used at serve time and comparing them against what the training pipeline reconstructs for the same moment. That is permanent infrastructure, and it is the reason feature stores exist.
Latency deserves a number of your own. Find out what the ad slot or page actually budgets for this call, then subtract network and serialisation. If the model gets tens of milliseconds, that constrains architecture more than any accuracy target will. Teams building this alongside other AI and data-driven product features consistently underestimate how much of the design is dictated by that budget rather than by model choice.
Consent is an engineering constraint, not a compliance paragraph
Third-party cookies have been degraded across browsers for years and the identity graphs built on them are correspondingly unreliable. The practical consequence is that the only data you can depend on is what your own properties collected, tied to your own identity, under a consent you can produce evidence of.
That changes architecture rather than adding a checkbox:
- Consent state travels with the event. Store what the user agreed to at capture time. Consent read at query time tells you nothing about whether you were allowed to collect the record in front of you.
- Withdrawal has to reach the training set. Stopping personalised serving is the easy half. Removing that user's contribution from the feature store and the next training run is the half that gets skipped, and the half a regulator asks about.
- Deletion needs a path through every derived artefact. Event log, feature store, cached recommendations, audiences exported to ad platforms. Anywhere a user ID was copied is somewhere deletion has to reach.
- Retention windows shrink the training set. Decide the window before you tune the model, because it changes what the model is able to learn.
- Exported audiences leak the most. Pushing a segment to an ad platform copies personal data outside your boundary, and consent scope has to follow it.
Then the constraint nobody states plainly: a consent-gated audience is smaller, and it is not a random sample of your traffic. Users who accept tracking differ systematically from those who do not. A model trained and evaluated only on consenting users looks better than it is, and the non-consenting share still has to be served something good.
The honest design accepts two tiers: a profiled tier with history, and a contextual tier with only the current page, the session, and the catalogue. Build the contextual tier properly rather than as a stub, because on many sites it serves the larger share of impressions. Handling personal data across both is ordinary data protection engineering, meaning where records live, who can read them, and whether you can prove deletion.
When a rules engine beats a model, and how to tell
There is a real threshold below which building any of this wastes money, and the honest version of it is not a single number. It is a relationship between three things.
Catalogue size against human capacity. If a merchandiser can still hold the catalogue in their head, roughly dozens to low hundreds of active items, their judgement beats a model. They know the new range is the priority, they know the margin, they know the return rate. A model has to infer all of that indirectly from noisy signals.
Interactions per item per week. This is the one that matters most. Collaborative methods need co-occurrence, and co-occurrence needs volume per item, not total traffic. Divide weekly interactions by active items and look at the median, not the mean, because the mean is carried by a few hero products. If the median item gets a handful of interactions a week, a learned model is fitting noise and will produce confident nonsense across the long tail.
How many decisions the system gets to make. With one ad slot and one creative, ranking has nowhere to express itself. Personalization pays off when there are many slots, many candidates, and repeat visits.
Below that threshold the alternative is not nothing. It is a small set of explicit rules over good data: recently viewed, category affinity from this session, stock-aware substitutes, a curated new arrivals block, and a suppression rule so people stop seeing the thing they already bought. That last rule alone removes the most common complaint about retargeting. It costs a fraction of a model programme and nobody has to be on call for a training pipeline.
Ongoing cost is what gets omitted from the business case. Our own published planning number, from operating Denti360 as a live product, is fifteen to twenty percent of the original build cost per year just to keep a system current, before new features. Personalization sits at the upper end of that band because its inputs move constantly: the catalogue changes, tracking changes, consent rules change, and the model decays on its own. If projected uplift does not clear that annual line, the project is not viable however good the demo looks. Price the whole commerce stack, using something like our e-commerce build cost guide, rather than the personalization feature alone.
If you cannot measure it with a holdout, you are not measuring it
The dashboards shipped with recommendation and retargeting tools report attributed conversions, and they almost always show a win. They are placed exactly where purchase intent is already highest, so they take credit for purchases that would have happened anyway.
The only measurement that answers the real question is a holdout: a fixed, randomly assigned slice of users who never see personalised placements, held stable over months, compared on revenue per user rather than click-through on the widget. Assign at user level, not session level, or people cross between arms and blur the result.
A few things keep holdout measurement honest:
- Measure at the right level. Click-through on a personalised module can rise while revenue per user stays flat, because you moved the same purchases to a different surface.
- Run long enough for novelty to decay. A new module gets attention because it is new. Early numbers overstate what month three looks like.
- Watch guardrails, not just the headline. Catalogue coverage, how concentrated impressions are on top items, return rate, complaints. A model can lift short-term revenue while shrinking the range of products anyone ever sees.
- Log the decision, not just the outcome. Store the candidate set, the scores, the model version and the selection probability for every impression. Without that you cannot debug a bad recommendation or evaluate a new model offline against logged traffic.
That last point pays for itself early. The gap between a team that can test a model change in a week and one that needs a month of live traffic per iteration is almost entirely whether they logged their own decisions from day one.
Trying to work out whether your catalogue and traffic actually support an AI ad personalization system, or whether a rules engine would do the job for a tenth of the cost? A Scoping Sprint ($2,300, two weeks) ends with an honest read on your event and identity layer, a clickable prototype, and a fixed quote. Or just start a conversation.