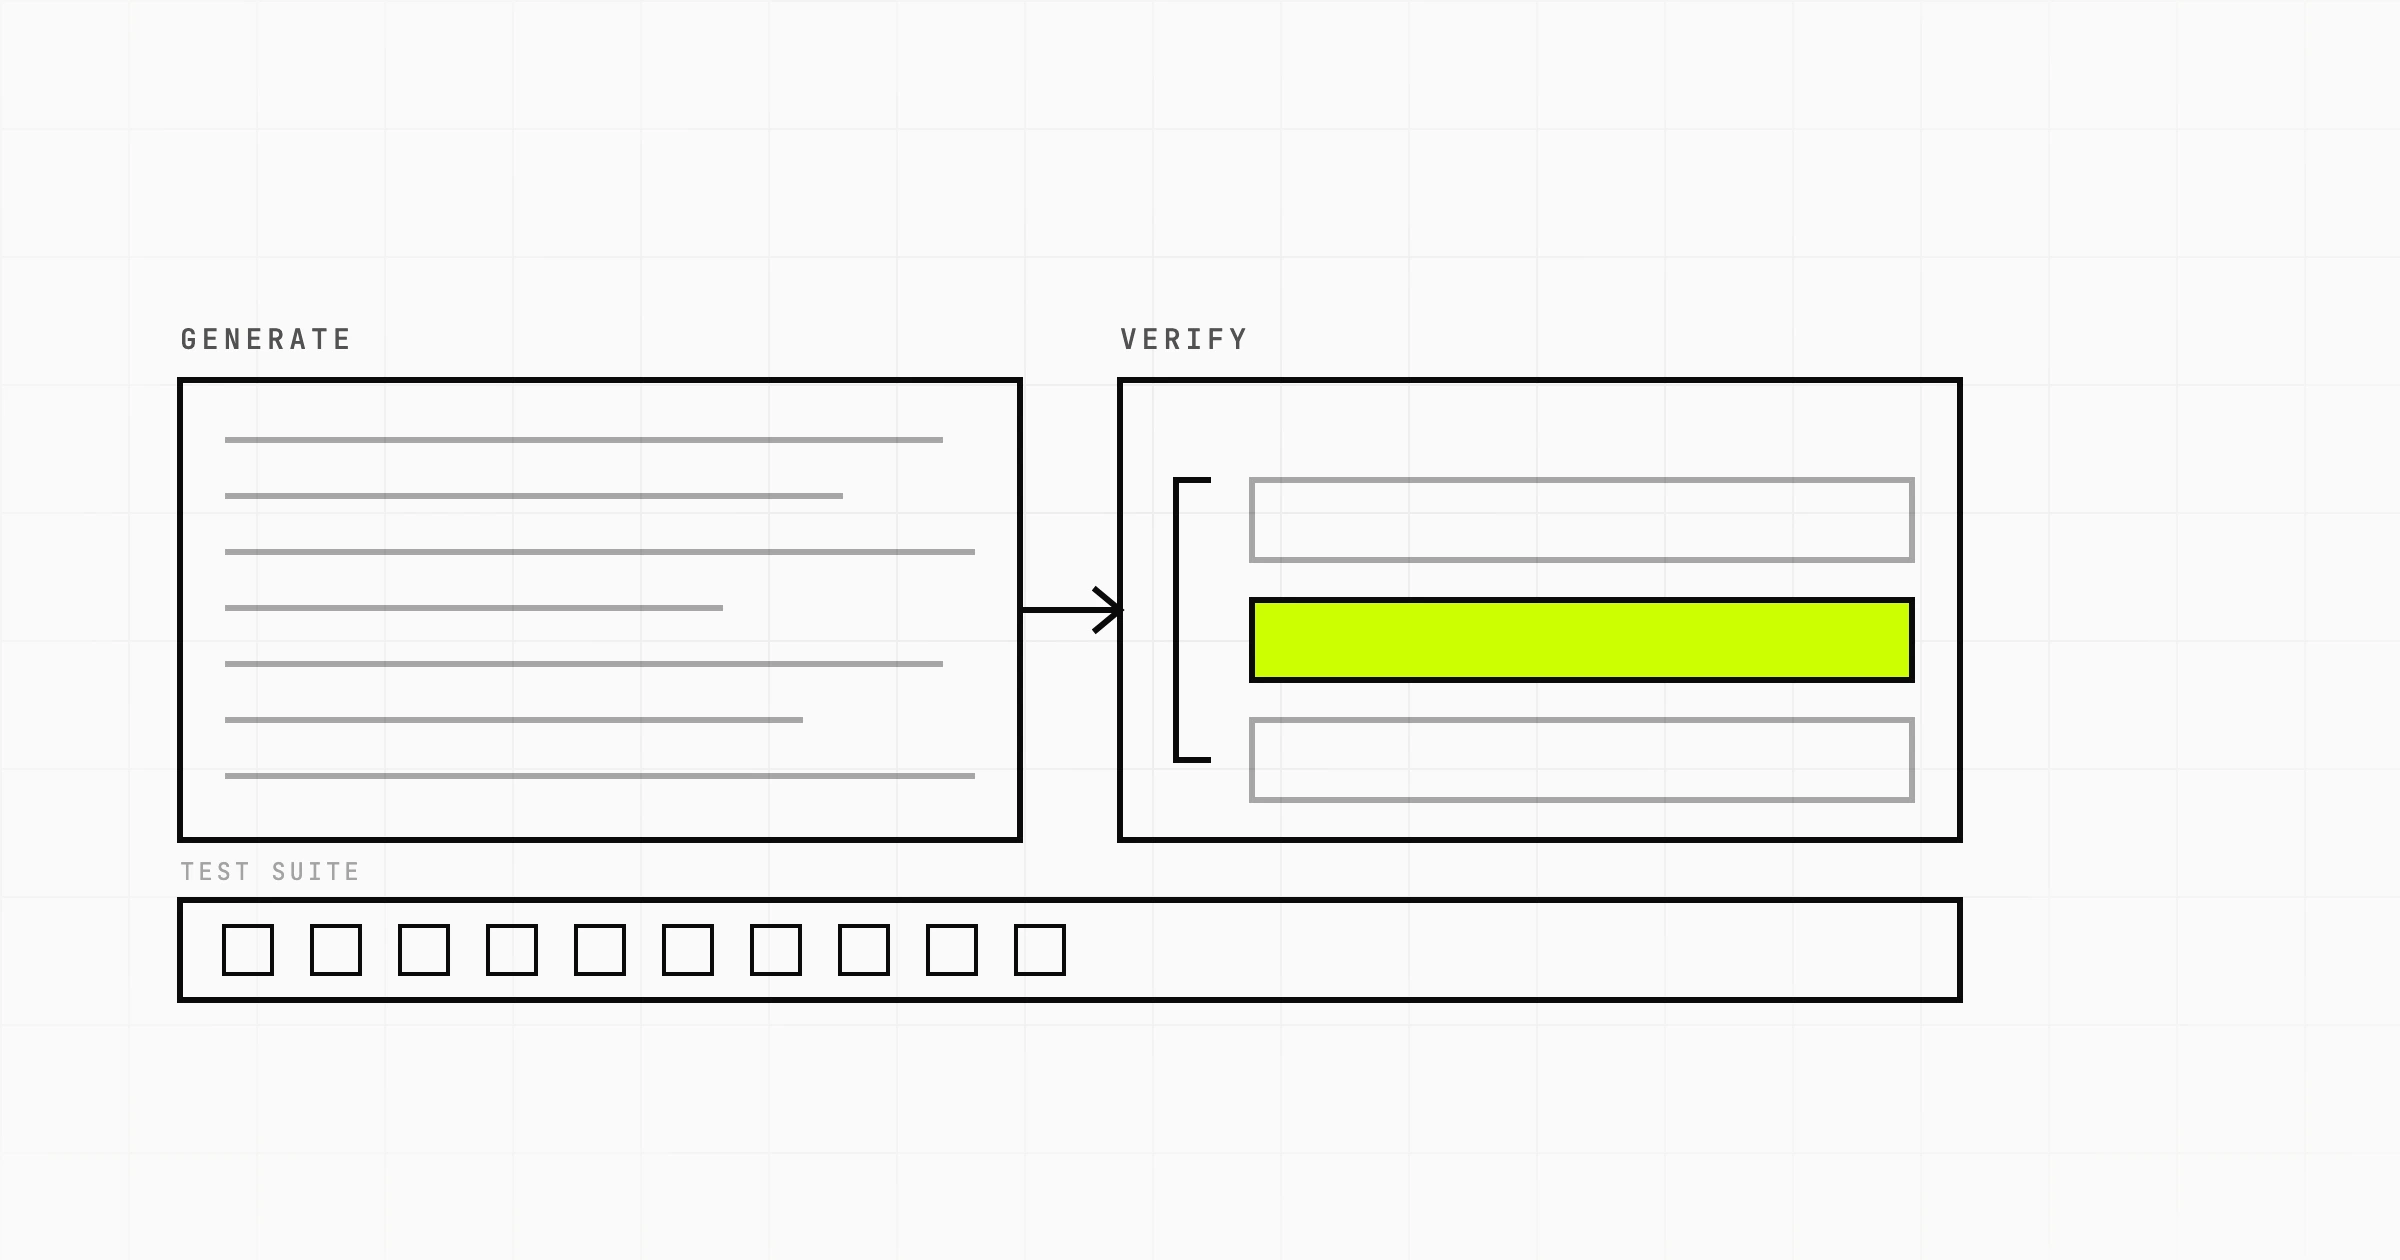
Generative AI changed the cost of writing code and left the cost of being sure the code is correct exactly where it was. Nearly every trend worth naming in web development over the last two years falls out of that one asymmetry.
Typing was never the slow part of shipping a web application. Deciding what the thing should do, agreeing on it, wiring it into a system that already exists, and proving it did not break anything: those were the slow parts. A tool that writes a React component in four seconds compresses one step of a pipeline whose other steps did not move. Plan around that honestly and you get a real speedup. Plan around the demo and you get a backlog of code nobody fully understands.
This is a working note on what actually shifted, for a developer who already uses these tools daily and a team lead deciding how far to push adoption. Two things it is not. It is not a tooling roundup: for that inside a specific stack, see AI tooling in a MERN codebase. And it is not a measurement framework, since measuring the return on AI coding tools is its own problem.
Where it speeds you up, and where it quietly costs you
The reliable predictor of whether generation helps on a given task is not how hard the task is. It is how long it takes you to know the output is wrong. Sort your work by that and the pattern is obvious within a week.
| Task | How fast you find out it is wrong | Net effect |
|---|---|---|
| Form, table and list components against an existing design system | Instantly, you look at it | Large gain |
| Type definitions and validation schemas from a sample payload | The compiler tells you | Large gain |
| One-off scripts, data backfills, CSV munging, log parsing | You run it on a copy | Large gain |
| Tests written against an implementation you already trust | They pass or they fail | Solid gain, with a caveat below |
| Explaining unfamiliar code, a regex, a query plan, a legacy module | You verify the claim against the code | Solid gain |
| Authorisation rules, ownership checks, tenant scoping | Possibly never, until a customer sees another customer's data | Net loss without full review |
| Money: pricing, proration, refunds, ledger entries | At reconciliation, weeks later | Net loss without full review |
| Concurrency, retries, idempotency, cache invalidation | Under load, in production, intermittently | Net loss without full review |
Notice that the top rows are not the easy tasks and the bottom rows are not the hard ones. A correct proration rule is not intellectually harder than a good data grid. The difference is that the grid is self-evident and the proration rule is not. Generation multiplies whatever feedback loop you already have. Where there is no loop, it multiplies nothing and adds volume.
The second real gain is quieter and rarely measured: reading. Pointing a model at a file you did not write and asking what calls it, what the nullable fields imply, and what happens if this promise rejects is faster than tracing it yourself, and the answer is checkable. On a legacy codebase that is often worth more than any generation.
Now the other direction. These are the failure modes that make generation a net loss, and they are worth naming precisely, because a failure mode with a name is something you can review for.
Confident wrong APIs
A method that does not exist, or did exist in an older major version of the library. TypeScript catches some of it. Anything dynamic, anything configured by an options object, anything where a valid-looking string key is silently ignored, none of that gets caught. Config objects for bundlers, ORMs and cloud SDKs are the usual site.
Plausible surface, wrong semantics
The code compiles, passes the happy path, and encodes a subtly different rule than the one you asked for. An off-by-one on an inclusive date range. A soft delete that filters in one query and not in the sibling one. A permission check that verifies the user is authenticated but not that the record belongs to them. This is the expensive category and it is invisible at a glance.
Silent over-engineering
Ask for a function and get a class, a factory, an options interface, a retry wrapper and a try/catch that swallows the error and returns null. Every layer is defensible alone. Together they add code you own forever, and the swallowed error will cost someone an afternoon in six months.
Convention drift
The model cannot see the unwritten rules your codebase runs on: which error class to throw, whether dates are stored as UTC strings or timestamps, which layer may talk to the database, that you always paginate. Each generated file drifts a little. Nothing breaks. A year later there are three ways of doing everything and nobody decided that.
The steering spiral
Two prompts in, the output is nearly right. Five prompts in, you are describing the solution in English at a level of detail that would have been faster to write in code, and you have lost the thread of your own design. A two-attempt rule helps: if the second try has not converged, close the panel and write it.
Debugging by plausible hypothesis
Given a stack trace and no reproduction, a model returns a confident and specific cause. It is sometimes right. When it is wrong, it is wrong in a way that reads exactly like being right, and you can lose an hour testing a theory you would never have formed. Use it to cluster errors and propose candidates. Do not let it conclude.
Code review is now the bottleneck, and it needs a different shape
Review used to run on an assumption nobody wrote down: that the author had already thought about every line, because typing it forced them to. That assumption is gone. A four hundred line diff can now represent ten minutes of human attention, and the reviewer cannot tell from the diff which ten minutes.
Worse, generated code reads better than human code at the surface. Consistent naming, complete JSDoc, tidy error handling, no commented-out experiment. That polish suppresses a reviewer's instinct. Sloppy human code signals where to look. Generated code gives no such signal, so reviewers skim.
What to change, given that:
- Cap the diff, not the time. Review throughput per person did not go up. If PR size doubles, review quality halves. Hold the old size limits and push back on large PRs harder than before.
- Read the tests first. If they only assert what the implementation happens to do, the PR is unverified no matter how it looks.
- Make the author the interpreter. A reviewer should be free to ask "what happens here if this call fails" about any line, and the author should answer without going back to the tool. If they cannot, the code is not ready, whether or not it is correct.
- Review the absences. The common generated defect is something missing: no pagination, no rate limit, no ownership check, no transaction around two writes that must both land.
- Grep for the tells. Unused parameters, unreachable error branches, defensive checks for states your types make impossible, a helper that duplicates one three directories away, magic values inlined rather than pulled from config.
One structural change is worth naming: the scarce resource on a team is now senior review attention, not senior writing throughput. That is worth thinking through before you extend a team with outside engineers, because review capacity has to grow with the code, not with the headcount.
Generated code needs a different kind of test, not more tests
Human bugs cluster where the author found the problem hard. You can feel where a colleague struggled by reading their code, and that is where you test. Generated bugs cluster somewhere else entirely: where the request was ambiguous. The model does not hesitate, so nothing in the output marks the spot.
Three consequences.
Do not generate tests from the implementation. If the same misunderstanding produces both the code and its tests, you get a green suite that proves only that the two agree. Write the test from the requirement, ideally before the implementation exists, then generate against it. Reversing that order is the most common way teams get a false sense of coverage.
Verify the test, not just the code. Break the implementation on purpose and check the suite goes red. A generated test that mocks the module under test, asserts a call count, or asserts expect(result).toBeDefined() is decoration. Ten seconds per test, and the highest-value ten seconds in the loop.
Shift weight toward integration and property tests. Unit tests inherit the author's assumptions, and generated ones inherit the model's. A test that exercises a real HTTP route against a real database catches the semantic drift that unit tests are structurally blind to. Property-based tests earn their keep for the same reason: generated inputs share nobody's mental model of a reasonable input. Boundaries to cover explicitly: empty collections, duplicate identifiers, a second concurrent write, a date crossing a timezone boundary, a user who owns nothing.
Generated UI lands better than generated backends, with one catch
Interface work is the easiest win available, because a browser is an instant oracle. A form with validation, a filterable table, an empty state, a responsive layout: you see whether it is right in seconds, and the cost of a wrong one is a redo, not a data incident.
The catch is that a model reaches for raw markup. Unless it is told otherwise, it will hand you a <button> with utility classes instead of your Button component, a fourth shade of grey that is not in your palette, and its own spacing scale. Nothing is broken. Your design system quietly stops being the source of truth, and six months of that is a refactor nobody budgeted.
Accessibility drifts the same way and matters more: a div with an onClick and no keyboard handler, an input with a placeholder and no label, a modal that does not trap focus or restore it on close, contrast that fails at the grey the model picked. Cheap to catch with a linter and an axe pass in CI, expensive to retrofit across fifty screens.
The fix is context, not vigilance. Give the model the component inventory and the tokens, ask for composition of existing components, and say explicitly that raw elements are not acceptable. What makes that possible is writing the design guidelines down instead of leaving them in people's heads. On Nestlet, our in-house marketplace for short-term residential leases, a full design guideline document was written up front precisely so the build could be handed to developers or to coding agents and come back consistent either way. That document is the thing you paste in, and it is worth writing before the first screen rather than after the fiftieth.
What it does to junior developers and to how a team learns a codebase
The old way a developer learned a system was by getting stuck in it. You read code because you had to, failed to find the thing, asked someone, and in the asking you built a map of the system and a relationship with the person who owned it. Generation removes the getting stuck. It also removes the map.
The failure mode is specific and you will recognise it: a developer who can ship a feature and cannot debug it. Everything works until it does not, and then there is no model of the system to reason from, only a tool that was not present when the request went out at 2am.
What seems to work:
- Give juniors bugs, not greenfield features. Debugging is the part of the job generation has barely touched, and it forces the map. A week of real bug tickets teaches more about a codebase than a month of new endpoints.
- Use the tool for reading, deliberately. "Explain this module and tell me what calls it" is a fast and legitimate way to onboard, and the answer is checkable against the code.
- Pair on review rather than on writing. Watching a senior read a diff and say what worries them transfers judgement. Watching one type does not, any more.
- Write the onboarding docs. They have two audiences now. The conventions file that stops a new hire guessing is the file that stops the model guessing.
None of this is an argument against giving juniors these tools. It is an argument that the apprenticeship path has to be rebuilt on purpose, because the accident that used to provide it is gone.
Estimates got less reliable, not more
Two things happened to estimation at once and they point in opposite directions. The mean came down, because the writing step genuinely compressed. The spread widened much more, because a task now either finishes in a tenth of the expected time or turns into an afternoon of steering, and you cannot tell which from the ticket. Teams that quoted the new mean and ignored the new spread have been missing dates.
The practical move is to estimate writing and verification as separate numbers, because only the first one compresses. If a feature was two days of writing and three days of review, integration, edge cases and QA, then halving the writing gets you from five days to four, not to two and a half. Anyone promising the second number is quoting the demo.
Be blunt too about which parts of a project were never typing-bound. Stakeholder decisions, third-party sandbox access, migrating data that is dirtier than anyone admitted, security and compliance review: none of these moved. On most web application builds they are what actually sets the date.
One more effect shows up after launch rather than during the build. Generation lowers the cost of adding code and does nothing about the cost of owning it. Our published planning figure from operating Denti360, our dental practice management product, is fifteen to twenty percent of the original build cost per year in ongoing engineering just to keep it current, before new features. That percentage applies to a codebase. If the codebase is larger because it was cheap to produce, the number it multiplies is larger too.
Context discipline turned into a real engineering skill
The part of this that looks like a fad and is not: choosing what the model sees is a skill, with a visible gap between people who have it and people who do not. It has nothing to do with clever phrasing. It is closer to writing a good ticket.
- Specify the interface first. Write the type signature, the schema, or the failing test yourself, then ask for the body. Almost all ambiguity failures are failures to pin the contract.
- Ask for a plan before code. A five-line plan is cheap to read and cheap to correct. Four hundred lines built on a wrong plan are not.
- Paste the real thing. The actual error, the actual schema, the actual neighbouring file that shows the convention. Summarising the context by hand is where most of the information gets lost.
- Keep the task small enough to hold in your head. "Build the checkout" produces something you cannot review. "Write the function that turns a cart into line items, given these types" produces something you can.
- Keep a current conventions file. Error handling, layering rules, naming, date storage, pagination defaults. It pays for itself with human joiners regardless.
- Treat everything the tool touches as untrusted. No production credentials in context, no agent with write access to production data, a human commit on every change.
The parts of the job it has not touched
Being specific about this matters, because this list is where the remaining value of an experienced engineer sits.
Deciding what to build is untouched. So is saying no to a feature, sequencing work against a launch date, and noticing that the thing the customer asked for is not the thing they need. Production ownership is untouched: the 2am page, the call on whether to roll back or fix forward, an incident where three things are wrong at once. Data migration is untouched, because the difficulty lives in the specific mess of your specific data. Legacy archaeology is untouched wherever the knowledge is in people rather than in the code.
Threat modelling is untouched, and this one is easy to get wrong: a model will happily generate a security control, but deciding which controls you need requires knowing what an attacker wants from your particular business. Naming your domain correctly is untouched. And so is accountability, because the name on the commit is a person's, and whether it should have shipped is theirs to answer.
The honest summary is that generative AI moved a competent developer's bottleneck from producing code to judging it. That is a genuinely good trade for anyone with judgement, a bad one for anyone who was relying on typing speed to look productive, and a reason to invest in review, tests and written conventions rather than in seat count.
Adopting these tools across a team and unsure what it does to your review capacity, your test strategy or your dates? A Scoping Sprint ($2,300, two weeks) ends with a technical plan built for your codebase and team, a clickable prototype, and a fixed quote for the build. Or just start a conversation.