Storefront personalization is mostly a set of decisions about surfaces, signals and latency. The model is the small part. Pick the wrong surface and the best ranker in the world has nothing to work with, because the visitor on that page is a stranger and will stay one for another ninety seconds.
The usual version of this project starts at the algorithm and works outwards. It should start at a page, a visitor, and an honest inventory of what you know at the millisecond that page renders. For a lot of ecommerce traffic the inventory is close to empty: a referrer, a landing URL, a device type, a coarse country from the IP address. No account, no order history, no clicks yet.
That is not an argument against personalization. It is an argument for putting it where the signal is. A returning customer with four orders and a saved size supports a different feature from an anonymous visitor who arrived forty milliseconds ago from a paid ad. Treating those as one problem is why so many rollouts ship a "recommended for you" row that serves the same eight bestsellers to everybody.
What follows is the applied side: which placements pay, what each needs, what real-time serving costs, how to measure it honestly, and which data you are allowed to use. For the engine underneath, the ladder from popularity counts to learned ranking, there is a separate piece on building the recommendation engine.
Start with an honest inventory of what you know
Write this down before you scope anything. Four tiers of visitor, four different feature sets.
- Anonymous, first touch. Landing URL, referrer and campaign parameters, device, language, coarse geography, time of day. A context, not a person.
- Anonymous, in session. The sequence of views, the filters applied, the sort order changed, and above all any search query typed. This is where the value hides, and the tier most stores ignore in favour of a stale profile.
- Returning, still anonymous. A first-party cookie gives you recently viewed items, an abandoned cart, category affinity. Fragile: the identifier resets on a new device or a private window, and in some regions you may not set it before consent.
- Identified. Order history, returns, size and fit, subscription state, email engagement, lifetime value band. Rich, and usually a minority of sessions.
Two things fall out of that list. First, the typed search query is the strongest and cheapest personalization signal you own. Someone who searches "waterproof walking boots size 9" has told you more in one line than six months of passive browsing would. If your search is a keyword match that never informs the rest of the session, fix that before you commission a model.
Second, intent lives in the session, not the profile. Retail intent is spiky. A person who bought a cot last spring is not shopping for cots now, and an affinity score built on a rolling year will keep insisting otherwise. Weight recent events far more heavily, and let the current session override the profile when they disagree.
Cold start here is a traffic-mix question
Before promising anything, measure two numbers: the share of sessions that are anonymous with no prior visit, and the share of revenue they produce. A feature that only works for logged-in returning customers might cover most of your revenue or almost none of it. For that cold tier, the useful moves are contextual rather than personal:
- Read the landing page as the intent. A visitor arriving on a category page from an ad for that category has declared a category. Order that page by what converts for that source, not by your global bestseller order.
- Personalize on the second click. Hold the first page constant and adapt once you have two or three events. The first load also has the tightest latency budget, so this is convenient as well as honest.
- Use cohort defaults instead of a blank. Country, currency, language, season and device are real constraints. Showing winter coats to a visitor in a southern-hemisphere summer needs no model to fix.
- Handle the new SKU deliberately. An item with no interactions never ranks up, so it never earns interactions. Reserve a slot for thin-data items and accept the small measured cost.
Rules and segments beat learned ranking more often than anyone admits
| Approach | What it is | Strengths | Where it breaks |
|---|---|---|---|
| Rules and merchandising logic | Explicit conditions: boost in-stock items, hide what cannot ship here, pin a collection for this campaign, demote high-return SKUs. | Ships in days. Fully explainable. A merchandiser changes it without a deploy. Needs no history. | Combinatorial rot. Forty rules interact unpredictably and nobody dares delete rule eleven. |
| Segments | A few named groups: new visitors, discount-led buyers, repeat category buyers, high-value accounts. Each gets a different ordering. | Coarse but sturdy. Explainable to the commercial team. Cheap in a nightly job. | Most visitors sit near a boundary, so assignment is arbitrary for a large slice. Segments go stale quietly. |
| Learned ranking | A model scoring candidates per request from user, item and context features, trained on logged interactions. | Finds patterns nobody encoded. Handles many weak signals at once. The real ceiling is here. | A system you operate, not a feature you add: training and serving parity, retraining, drift monitoring, silent decay when a field changes meaning. |
Rules come first, because you need the suppression and business-constraint layer regardless. However good your ranker gets, you still need somewhere to say "never recommend this with that" and "do not show what we cannot ship". Build it on day one and put everything later behind it.
Then segments, because they give you your first evidence that differentiated treatment moves anything. If two well-chosen segments with hand-written orderings produce no lift over one global ordering, a model is unlikely to rescue the idea, and that is worth knowing after two weeks rather than two quarters.
One rule nearly always worth its weight: put inventory and margin into the ranking. A recommender optimised purely for clicks will push items that are out of stock in most sizes, or whose return rate makes the sale unprofitable. Those are ranking inputs, not afterthoughts, and they are why a storefront is not a content feed.
Where personalization goes on the page, surface by surface
Search results
The highest-intent surface in the store and usually the least personalized. The visitor has typed what they want, so most of the work is interpretation: synonyms, misspellings, attribute extraction, and a null-result case better than an empty page. Layer personalization on as a tiebreak only, ordering equally relevant results by what this visitor tends to buy. Never let it push a less relevant result above a more relevant one, because search is where users notice wrongness instantly.
Category and collection ordering
The largest surface by pageviews, and cheap, because you are permuting a list you already fetch. Rank on a blend of inferred intent, conversion rate, stock depth and margin. Two constraints that are easy to miss: keep the order stable within a session, since a list that reshuffles on back-navigation feels broken, and check what a crawler with no cookies and no consent sees.
Product detail page rows
Two distinct jobs that teams merge into one row. "Similar items" helps a visitor who has not found the right thing yet and belongs high on a page reached from search. "Goes with this" helps a visitor who has already decided and belongs near the cart action. Complementary items are worth more per slot than near-duplicates, and an unconstrained similarity model will produce nine variations of the same shirt.
Cart and checkout
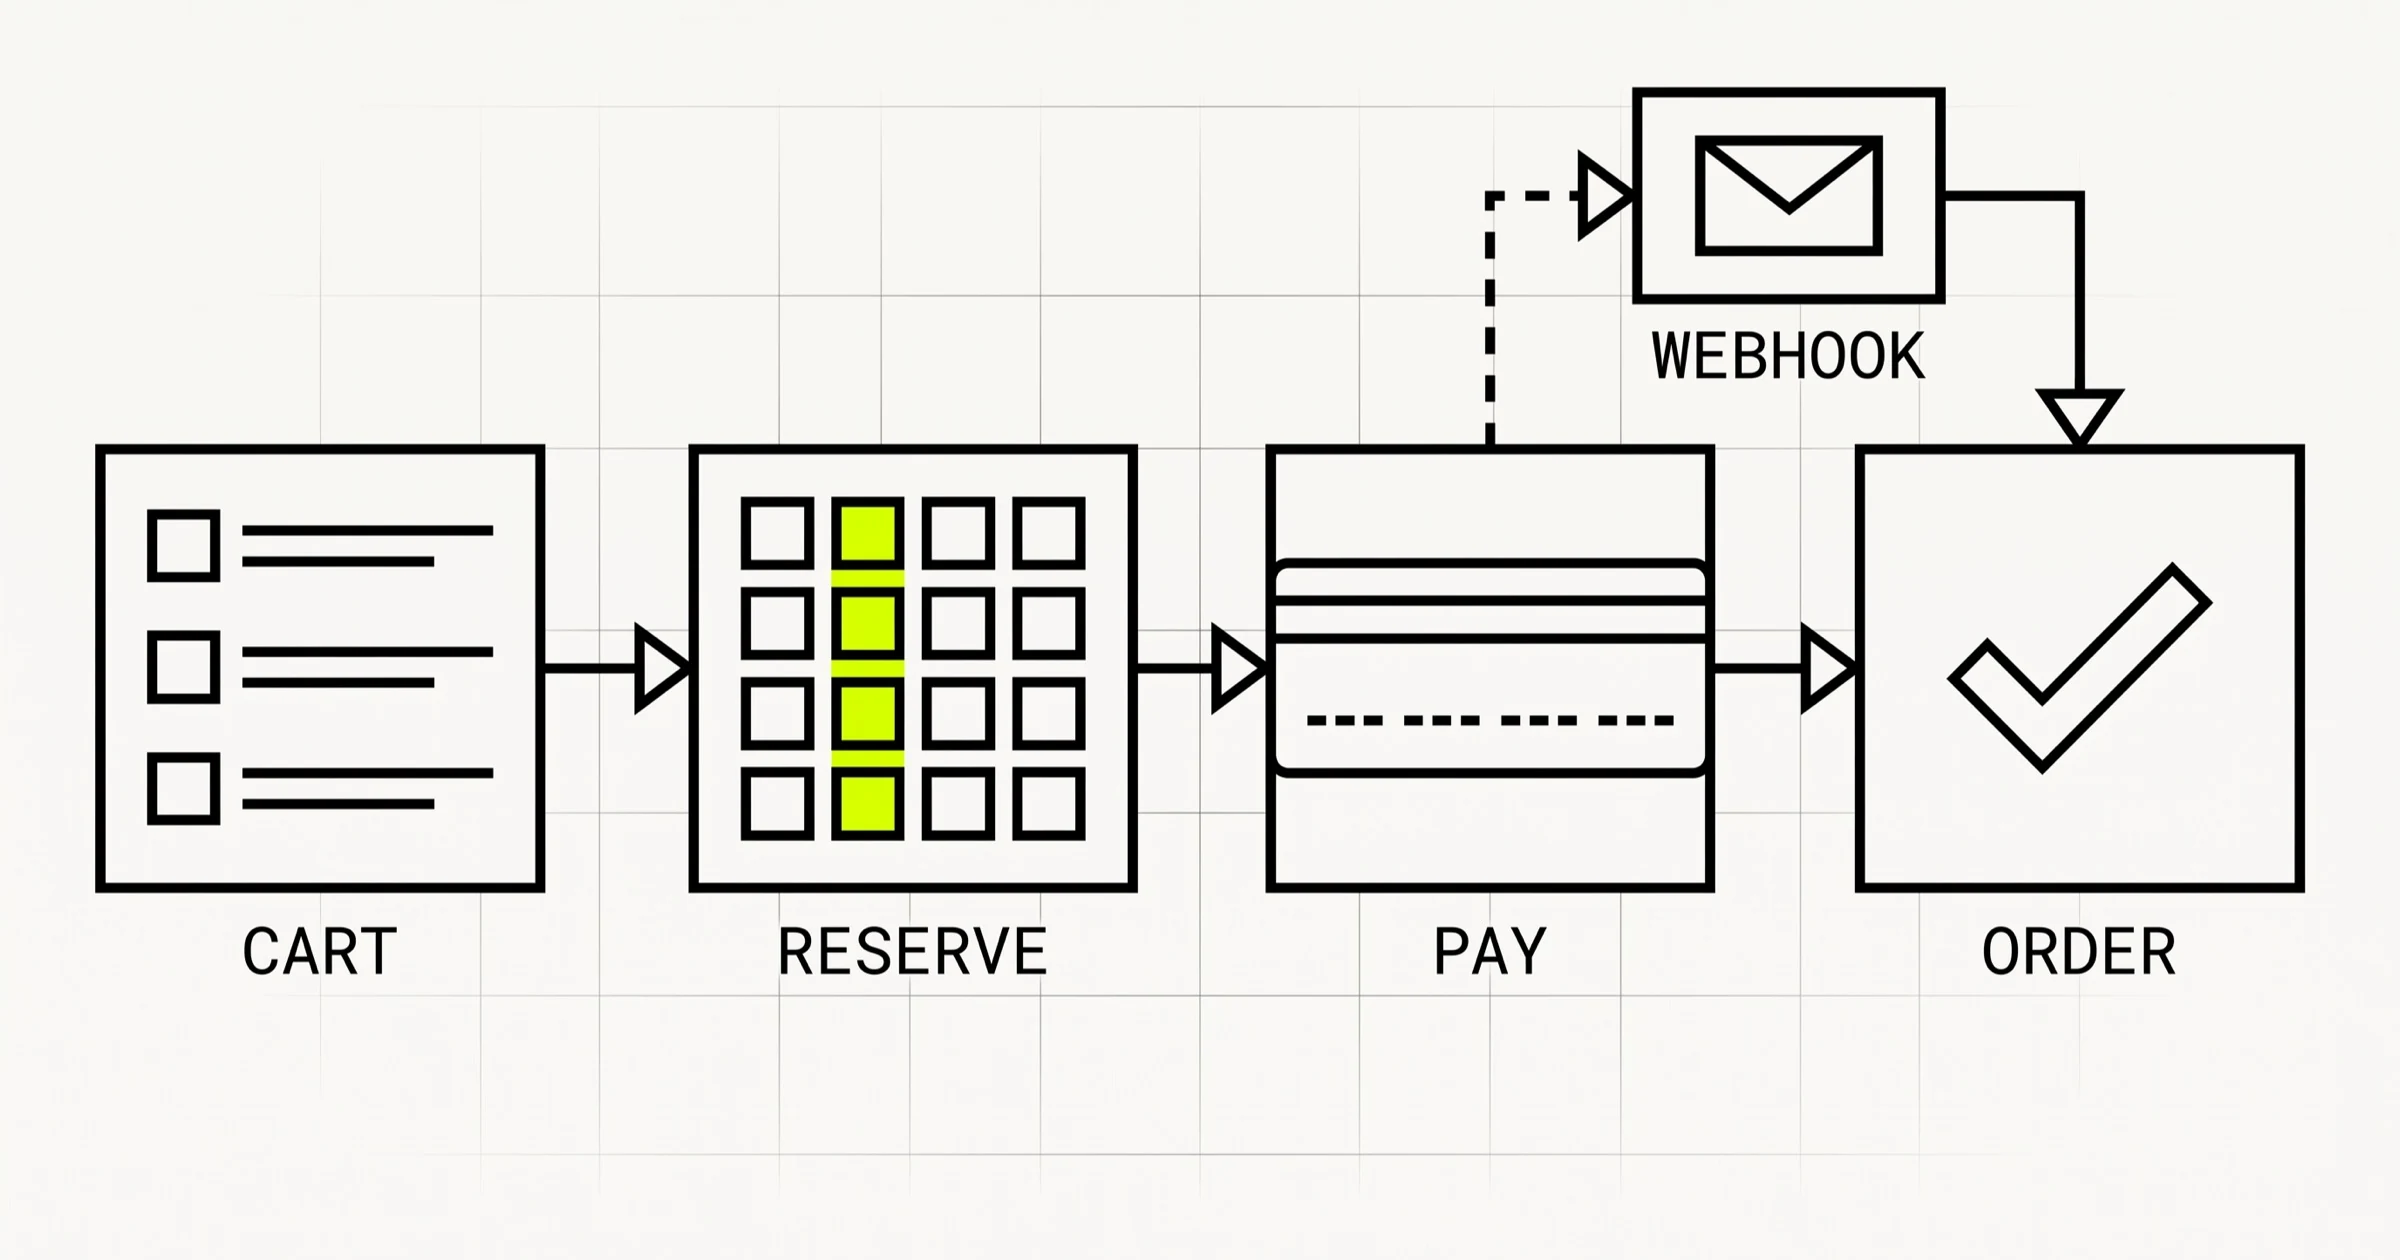
The narrowest and most dangerous surface. A relevant, low-friction add converts well because payment intent already exists. A distracting one costs you the order. Keep it to things needing no research: consumables, accessories for what is in the cart, a size up, a free-shipping nudge. Never introduce a new decision inside the payment flow. That constraint belongs in the storefront and checkout architecture rather than bolted on later.
Post-purchase and lifecycle messaging
Often the best return of all and the most neglected, because it has no latency budget at all. The confirmation page, the shipping notification, a replenishment reminder timed to the consumption cycle, a back-in-stock alert for the exact variant they wanted. You can run the heaviest model you like, offline, with the full profile, and no page gets slower.
Real time or batch, and what real time actually costs
Real time means computing a decision per request from events in the current session. Batch means precomputing an answer per visitor or item on a schedule and serving a key lookup. The gap is not accuracy, it is operational cost, and it is large.
Batch needs a job, a cache, and a fallback for misses. Real time needs a live event pipeline with tight tail latency, a feature store readable in single-digit milliseconds, a scoring service on the critical path of your render, and defined behaviour for each of those failing during a sale. It also adds a second copy of your feature logic, which is where training and serving drift begins.
The useful middle is hybrid: precompute candidates and scores in batch, then rerank a short list at request time against the current session. You get intent responsiveness, the thing real time is actually for, without a model server in the render path. Most stores should sit here and many never need to leave batch.
Real time earns its cost on search and browse within a session, on stock and price accuracy where showing an unavailable item is a concrete failure, and on anything triggered by an action that just happened. It does not earn it on profile affinities that barely move day to day, on email sends, or on most homepage layout. Be specific about which of your surfaces is which, because "we need real-time personalization" is usually an unexamined assumption that turns into a line on the infrastructure bill. Price that difference when you plan, alongside the rest of the ecommerce build and running cost.
The latency budget is the whole argument
Personalization competes for the same milliseconds as the page. Conversion falls as pages slow down, and the slowdown hits every visitor while the gain reaches only the subset where you had usable signal. A feature can therefore show a healthy click-through on its own row and still be net negative for the store. Set the budget before you build and treat it as a hard limit:
- Put a number on it and measure the tail. A budget expressed as an average is meaningless. Hold the 95th and 99th percentile, because those are the requests that time out in your busiest hour.
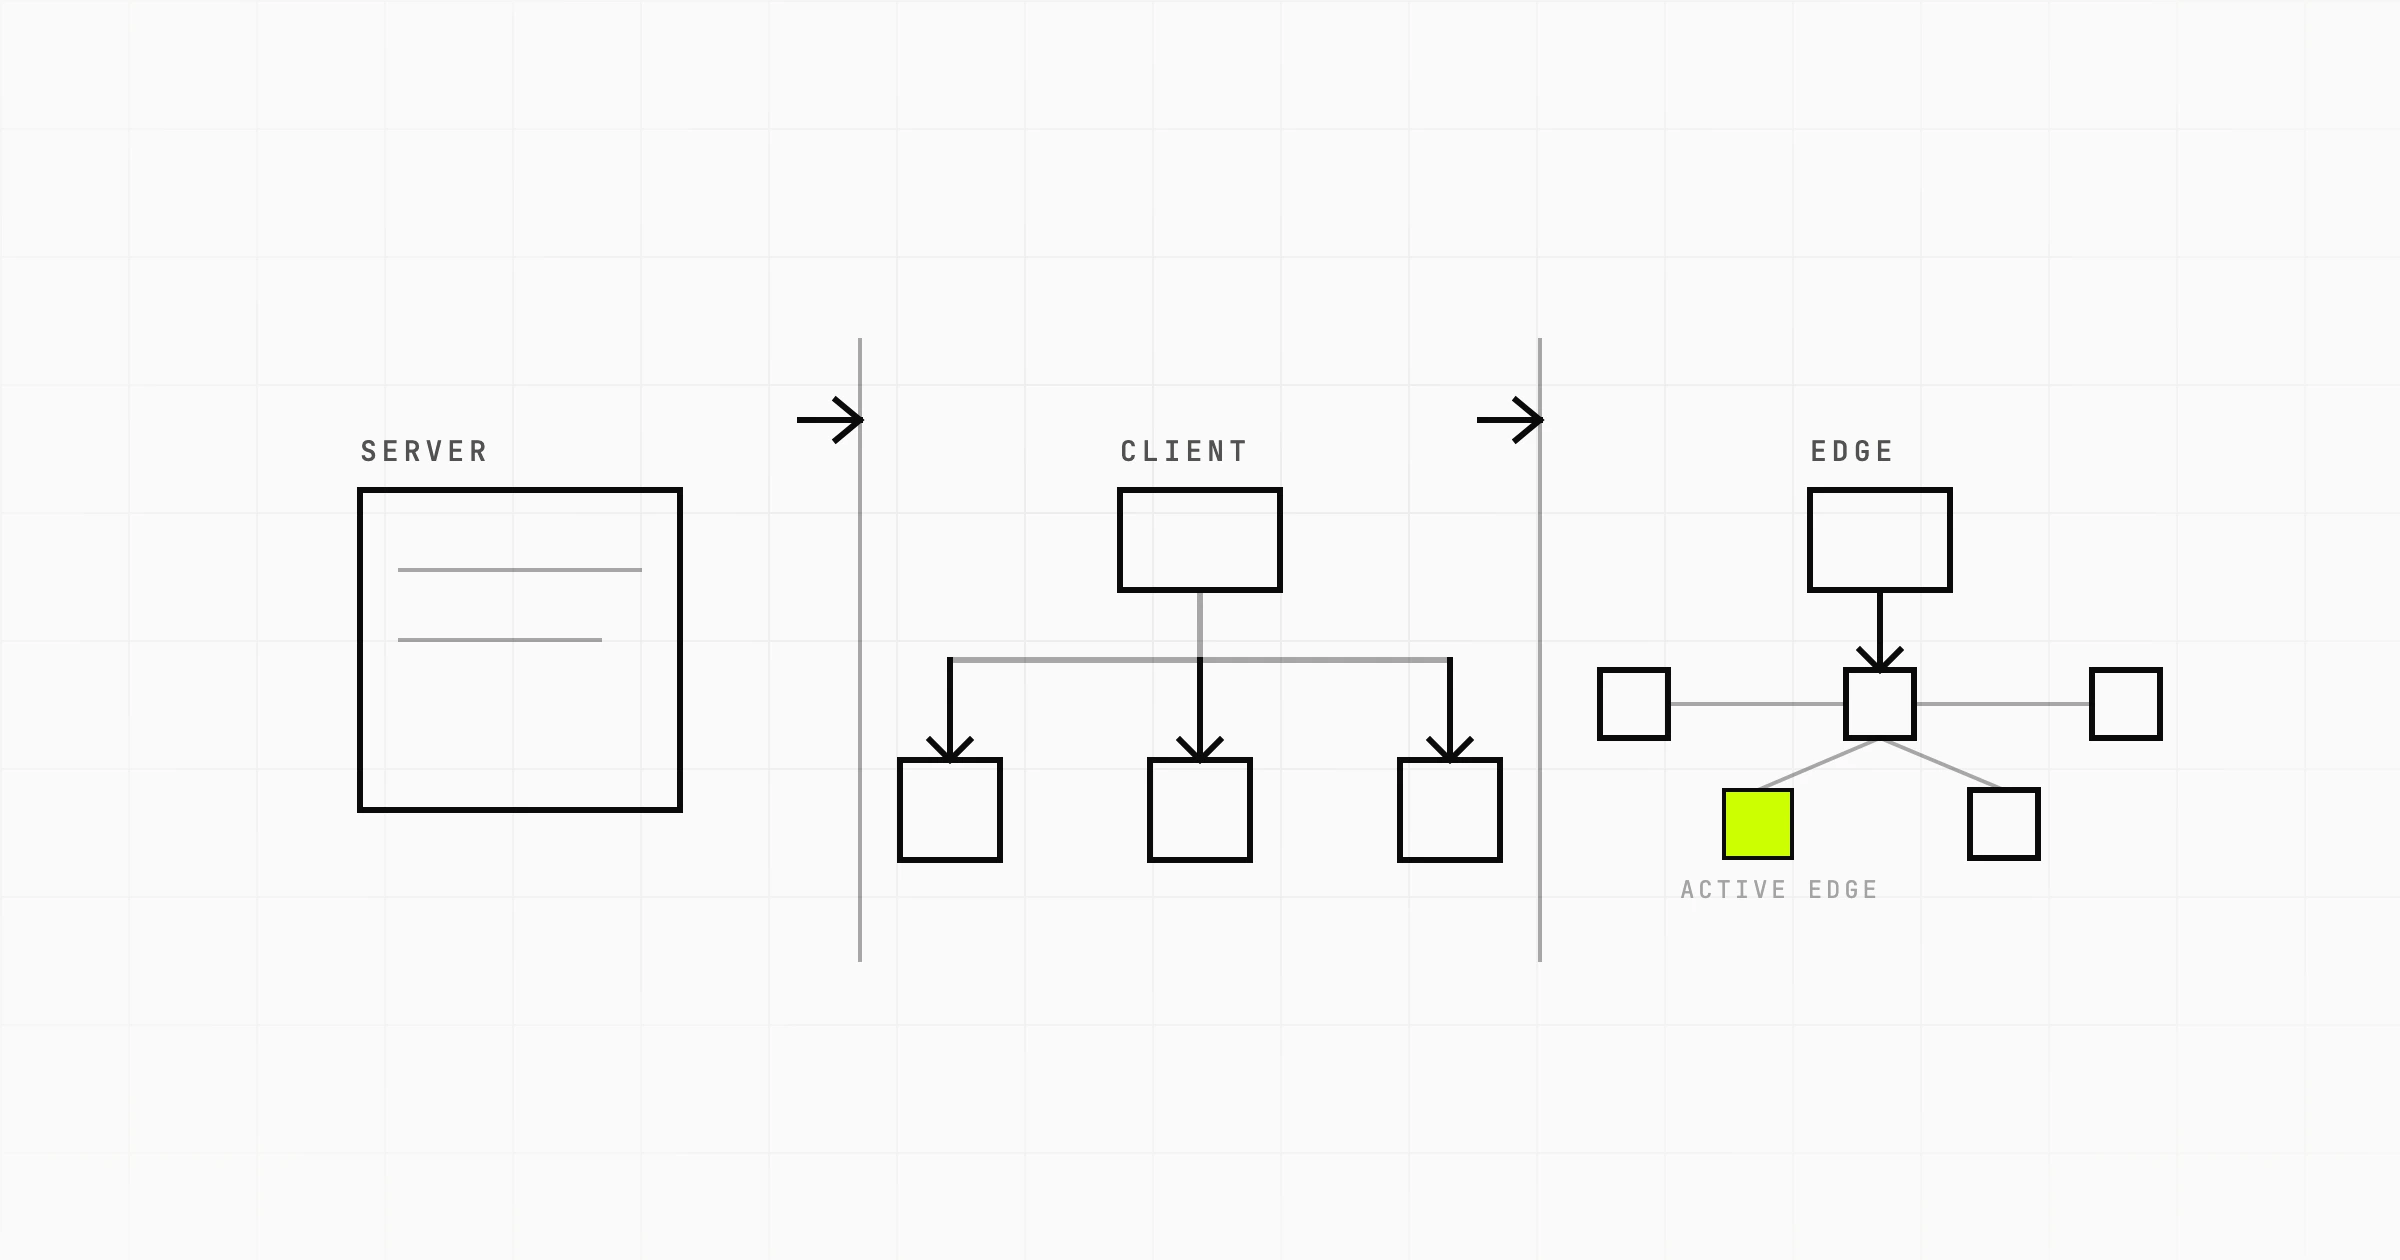
- Never block first paint. Render with a default ordering and let personalized content arrive after, or resolve it at the edge before the HTML is built. What you must not do is reflow the main content once it arrives: a grid that shifts under the user's thumb costs layout stability.
- Fail open, always. Every call needs a timeout in tens of milliseconds and a cached default behind it. Test that path deliberately instead of discovering it during a campaign.
- Count the round trips. Three calls for three personalized rows is three chances to blow the budget. Batch them into one request or resolve them in the same edge function.
This is one of the real arguments for a decoupled front end: a headless storefront lets you resolve personalization at the edge with the page instead of firing a client-side call after everything else loads. Architecture, not tuning.
Without a holdout you do not have a result, you have a story
The measurement failure is specific and almost universal. Someone reports that the personalized row has a high click-through rate and carries a share of revenue. Both are true and neither tells you anything, because the items in that row are your bestsellers and those visitors would very likely have bought them anyway. Attribution to a row is not incremental revenue.
What does tell you something:
- A permanent holdout. Keep a slice of traffic on the non-personalized experience indefinitely, not for the length of one experiment. Without it you cannot answer in six months whether the system still contributes, and sometimes the answer is that it stopped.
- Session and revenue metrics, not row metrics. Revenue per session, conversion rate, units per order, for the whole group. A row can win while the session loses, by pulling attention off a better path.
- Returns and margin after the fact. Apparel makes this vivid. A recommender tuned on orders learns to push items that come back, and the win disappears weeks later in a different report.
- Catalogue coverage and guard metrics. If only a thin slice of your catalogue ever reaches a personalized slot, you have built a bestseller chart with extra infrastructure. Watch tail latency and search usage alongside it.
Randomize by visitor rather than session, keep the assignment stable, and be patient. Conversion is a low-rate event and purchase cycles are long, so a two-day test on one row tells you nothing.
Consent decides which signals you are allowed to use
Under the European and UK regimes, non-essential tracking needs consent before it happens, so a visitor who declines may get no personalization cookie at all. Build for that as a first-class path: contextual personalization from the landing page and the in-session sequence needs no identifier. Design the cold tier well and the consent problem shrinks, because the cold tier and the no-consent tier are the same engineering problem.
- Purpose and retention. State what each event is for and how long you keep it. Ranking history does not need to live forever, and a shorter window often ranks better because intent decays.
- Where the data goes. Sending behavioural events to a third-party vendor is a processing arrangement with contractual and regional implications. Check it before you build, not when a security questionnaire lands.
- Keep sensitive inferences out. Health, pregnancy, religion and financial distress can all be inferred from a browsing session, and surfacing such an inference in a recommendation row is a serious problem regardless of accuracy. Suppress those categories at the rules layer.
- Personalized ranking is not personalized pricing. Reordering results per visitor is ordinary merchandising. Showing different prices or discounts to different people carries disclosure duties in several markets. Keep the two systems separate.
- Honour deletion end to end. A deletion request must reach your event log, feature store and precomputed recommendation tables, not only the customer record.
What to build first
| Your situation | Build this | Serving mode | Rough effort |
|---|---|---|---|
| Search is keyword matching and the query is never used again | Query interpretation: synonyms, misspellings, attribute extraction, a real null-result fallback | Request time, already in budget | Two to four weeks |
| No event log, or one written only from the browser | A server-side append-only event stream before anything else. You cannot backfill history you never wrote down | Not applicable | One to two weeks |
| Rules exist but nothing is suppressed or constrained | A merchandising and suppression layer in front of everything: stock, shipping eligibility, blocked pairings, sensitive categories | Batch plus a request-time filter | One to two weeks |
| No evidence that differentiated treatment does anything | Two or three segments with hand-written orderings, behind a flag, with a holdout | Nightly batch | Two to three weeks |
| Lifecycle messaging is generic or absent | Post-purchase and replenishment personalization, plus back-in-stock for the exact variant | Batch, no latency budget | Two to four weeks |
| Segments live and measured, ceiling visible, real traffic | Learned reranking over precomputed candidates, with returns and margin in the objective | Hybrid: batch candidates, request-time rerank | A quarter, then ongoing |
| Personalization live and page latency climbing | Stop adding surfaces. Consolidate calls, set a tail budget, add fail-open defaults, re-measure against the holdout | Edge or server-side | Two to three weeks |
Effort there assumes the event stream exists; if it does not, add its row to every line below it. And every row is an ongoing cost, not a one-off: catalogues change and behaviour drifts, so a pipeline nobody has looked at in a year serves last year's intent with full confidence.
The pattern across all of it: own your event stream and your rules layer, keep the model swappable, and put the feature where you actually have signal. Most of the gain in retail and ecommerce engineering work comes from those three decisions rather than the choice of ranker, and they are the ones that are expensive to change later.
Trying to work out which personalization surface your storefront data can actually support? A Scoping Sprint ($2,300, two weeks) ends with a personalization plan by surface, signal and latency budget made for your case, a prototype, and a fixed quote. Or just start a conversation.